Artificial Intelligence
Google Cloud and NVIDIA Launch General Availability of Vera Rubin AI Supercomputing Clusters
Ultra-scale liquid-cooled datacenter pods expand high-throughput model training capacity across North America and Europe.
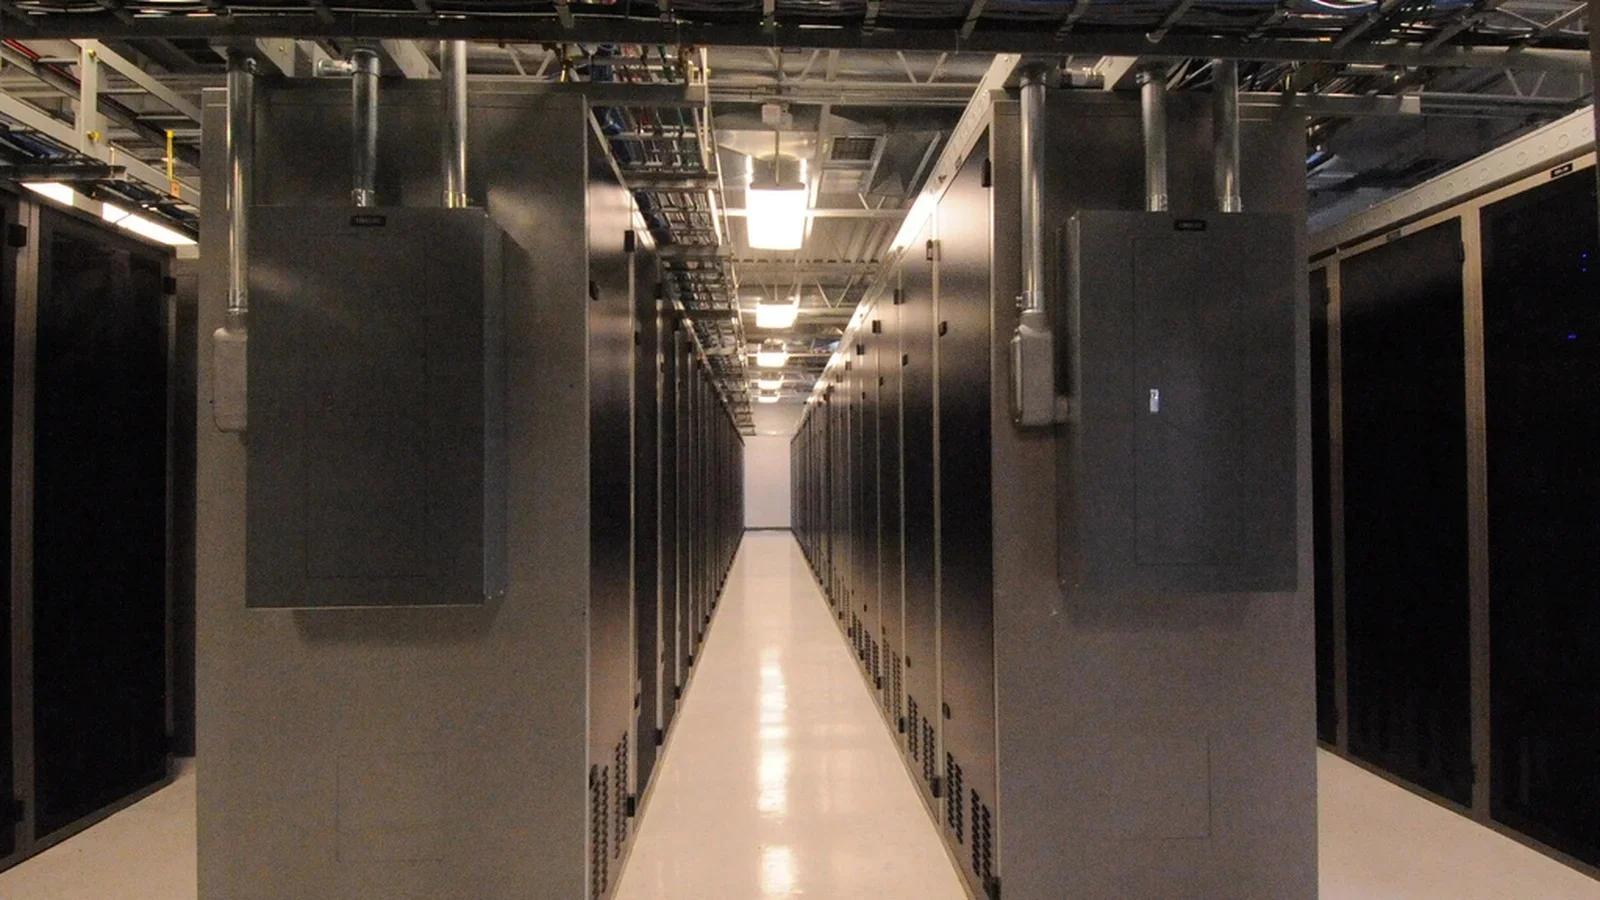
Google Cloud and NVIDIA announced the worldwide commercial availability of their co-engineered Vera Rubin AI supercomputing infrastructure on Wednesday, October 21, delivering massive multi-node computing clusters designed to accelerate the training and low-latency inference of trillion-parameter frontier artificial intelligence models. The deployment introduces custom liquid-cooled server architectures engineered to support unprecedented thermal power densities while reducing datacenter water consumption across regional server facilities.
Technical specifications released by Google Cloud engineering leadership detail rack configurations that connect thousands of Vera Rubin tensor accelerators via fifth-generation NVLink and custom optical transceivers, delivering 1.8 terabytes per second of bidirectional chip-to-chip bandwidth. The unified compute topology eliminates traditional network latency bottlenecks during distributed checkpointing, allowing frontier AI laboratories in San Francisco, Mountain View, and Seattle to execute multi-week training runs with near-linear scaling efficiency.
Enterprise cloud architects and energy department officials highlighted that the infrastructure deployment directly addresses persistent global GPU supply shortages, offering reserved instance commitments with guaranteed compute availability and zero downtime migration guarantees. The platform integrates seamlessly with Google Cloud's Vertex AI orchestration program and Kubernetes Engine, enabling machine learning engineers to automate model parallelization and fault recovery without managing underlying hardware drivers.
Google Cloud confirmed that customer onboarding for dedicated Vera Rubin compute pods has opened for enterprise AI developers and research institutions through regional cloud console portals. Detailed pricing tiers, carbon efficiency metrics, and hardware performance whitepapers are published online at cloud.google.com/ai-infrastructure. Technical inquiries regarding compute allocation quotas should be directed to the Google Cloud AI solutions team in Sunnyvale.
Comments (0)
No comments yet. Be the first to share a thought on this story.
Request a correctionContact the newsroom
Keep reading
UC Berkeley Professors Propose Multilateral Governance Framework for Global Pause on Frontier AI
Interdisciplinary study recommends international hardware tracking and cryptographic compute verification to halt uncontrollable model scaling.